 Przez
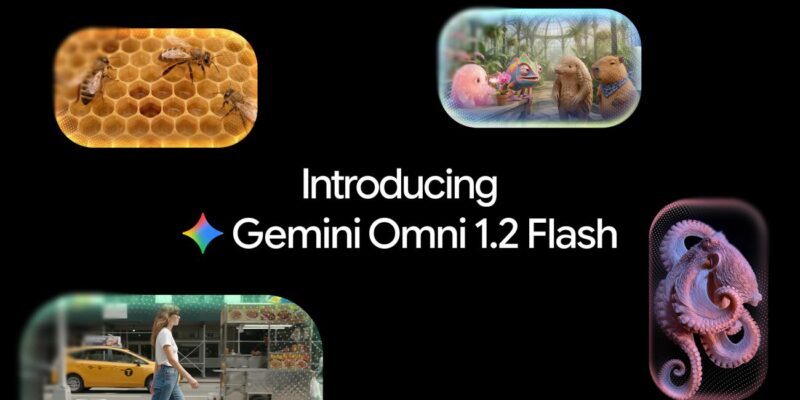
Ogłoszono wydanie Gemini Omni 1.2 Flash przeznaczonego do dłuższych klipów
Google DeepMind has announced Gemini Omni 1.2 Flash, describing it as a fast, cost-effective model that can handle longer clips. Based on the limited information available in the source material, the key takeaway is the company’s positioning of this release around lower-latency multimodal processing and longer-context media inputs rather than a fully detailed technical benchmark.
What is confirmed from the source input is narrow: the product name, the version number, and Google DeepMind’s framing of the model as both efficient and suited to longer clips. The announcement title suggests a practical focus on video or other time-based media workflows, but the source material provided here does not include specifications, pricing, context-window figures, benchmark results, regional availability, or deployment details.
What the announcement appears to signal
Even with sparse details, the wording matters. A model marketed as fast and cost-effective usually targets developers and businesses that need multimodal AI features without the expense or latency associated with larger systems. The reference to longer clips also points to use cases where short-context media understanding has been a limitation.
A hypothetical example: a media team could use a model in this category to process longer product demo videos, training recordings, or customer support clips and generate summaries or metadata faster than with heavier models. That is an illustration of the likely workflow fit, not a confirmed deployment or capability list for this release.
Co pozostaje niejasne
The source input does not say how Gemini Omni 1.2 Flash compares with earlier Gemini Omni versions, rival multimodal models, or Google’s other Flash-branded systems. It also leaves open important questions for buyers and developers, including throughput limits, supported modalities, enterprise controls, API access, and whether “longer clips” refers to minutes, hours, or another measurement.
Until fuller documentation is available, readers should treat this as an announcement of positioning rather than a complete product evaluation. The business relevance is clear, but the operational implications will depend on technical details that were not included in the supplied source text.
Could lower-cost long-clip multimodal models shift AI adoption from short demos to routine media operations inside enterprises?
Źródło: original reporting by Google DeepMind. Powyższe stwierdzenia odzwierciedlają informacje zawarte w tym źródle.
Zapoznaj się z powiązanymi artykułami w naszej sekcji Sekcja wiadomości o sztucznej inteligencji.
Praktyczne zastosowania sztucznej inteligencji
Partner note — Implementi.ai: When multimodal models get faster and cheaper, one practical challenge for businesses is turning meetings, recordings, and internal discussions into usable follow-up actions. For teams exploring that workflow, przebieg pracy asystenta spotkań opartego na sztucznej inteligencji can help structure notes, action items, and summaries around real operational processes.


